
Screen Scraping: How It Works & Why It Can Be Risky
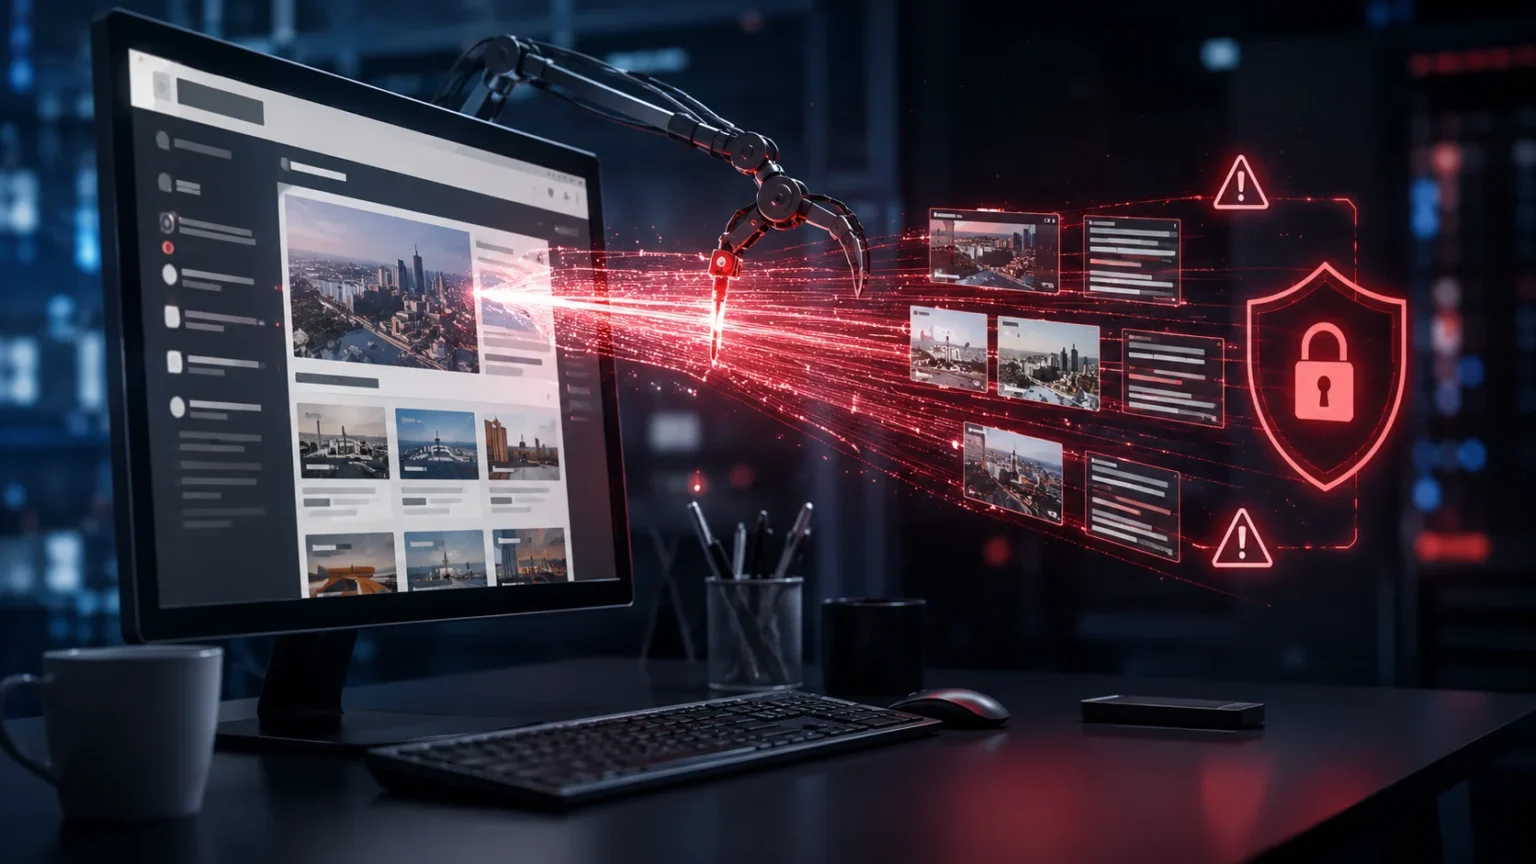
Screen scraping is a method of extracting information directly from what appears on a computer screen, website, application, or digital interface. Instead of receiving data through a structured connection such as an API, scraping software reads visible information and converts it into data that another program can store, analyze, or process.
The technology has existed for decades, but it remains relevant because businesses still rely on legacy applications, websites, dashboards, and systems that do not provide convenient data integrations. Screen scraping can bridge these gaps by allowing automation tools to interact with information that would otherwise require someone to manually copy, type, or transfer.
However, convenience comes with important trade-offs. A screen scraper may depend heavily on page layouts, login credentials, interface elements, HTML structures, and other components that can suddenly change. Even small interface updates can cause an automated scraping process to capture incorrect information or stop functioning entirely.
There are also security, privacy, compliance, and operational concerns that organizations need to understand before using this technique. Knowing how screen scraping works, how it differs from web scraping and APIs, and where its biggest risks appear can help businesses make better automation and data-access decisions.
What Is Screen Scraping?
Screen scraping refers to the automated process of collecting information displayed through a user interface. Software identifies particular fields, text, tables, buttons, or other visible elements and then extracts or interacts with them. The captured information can later be transferred into databases, spreadsheets, business applications, or automated workflows.
Traditional screen scrapers were commonly used with older terminal-based computer systems. Instead of modern graphical interfaces, employees might work with fixed-position text displayed on screens. Scraping tools learned where particular information appeared and extracted it automatically, reducing the need for repetitive manual data entry.
Modern screen scraping has expanded considerably. Automation software can interact with websites, browser applications, financial portals, enterprise software, customer dashboards, and desktop programs. Technologies such as robotic process automation can recognize interface elements and perform actions that imitate how a human user navigates software.
This makes screen data extraction particularly useful when no application programming interface is available. However, the technique usually depends on the presentation layer rather than the underlying structured data source, making screen-based automation more sensitive to interface changes and other technical problems.
How Does Screen Scraping Work?
A screen scraping tool begins by identifying the digital location containing the required information. This might be a website, desktop program, customer portal, internal business application, or legacy system. Depending on the technology being used, the scraper may detect text positions, HTML elements, interface controls, images, or accessibility properties.
The automation then navigates the interface much like a person would. It may open pages, enter credentials, click menus, select filters, copy values, and move between screens. More advanced automation platforms can also use rules or computer vision to recognize changing interface elements rather than relying entirely on fixed positions.
Once the required information appears, the scraper captures specific data points. These could include account balances, transaction details, customer records, product information, order statuses, pricing data, invoice numbers, or other business information. The extracted data is normally cleaned and converted into a format another application can understand.
The final step involves sending that data to its destination. Information might be entered into customer relationship management software, stored in a database, added to a spreadsheet, or used to trigger another automated process. In this way, screen scraping often acts as a bridge between systems that were never designed to communicate directly.
Screen Scraping vs Web Scraping: What Is the Difference?
Screen scraping and web scraping are sometimes treated as interchangeable terms, but they are not exactly the same. Screen scraping focuses primarily on information presented through an interface, while web scraping typically extracts information from the underlying structure of web pages, including HTML, CSS selectors, and other website elements.
A web scraper may request a page and parse its HTML without visually interacting with the site as a person would. It can identify headings, product listings, tables, links, metadata, and other structured elements. This approach is commonly used for data aggregation, market research, search monitoring, and publicly accessible website analysis.
Screen scraping is often more focused on mimicking user interaction. The software may need to log into an application, navigate menus, click buttons, and read information displayed after specific actions. This makes it especially useful for software environments where direct access to structured underlying data is limited.
Both techniques can experience similar challenges, including website changes, access restrictions, authentication requirements, privacy considerations, and data quality problems. However, screen automation may be particularly fragile because it frequently depends on exact interface layouts and workflows that developers can modify without warning.
Screen Scraping vs APIs: Why APIs Are Usually More Reliable
An API allows two software systems to exchange information through predefined rules and structured requests. Instead of reading information displayed on a screen, an application can request specific data directly from another application’s backend. The receiving system then returns information in a structured format such as JSON or XML.
This structured communication generally makes APIs more stable than screen scraping. Developers know which fields are available, how authentication works, what data formats will be returned, and how requests should be submitted. Well-maintained APIs may also include documentation, versioning, permissions, error messages, and security controls.
Screen scraping lacks many of these advantages because it interacts with an interface designed primarily for people rather than software. If a button moves, a page is redesigned, a field name changes, or an additional authentication step appears, the automated workflow may fail even though the underlying application continues working normally.
Nevertheless, APIs are not always available. Some older platforms were developed long before API-based integrations became common, while other services intentionally limit external data access. In such situations, organizations sometimes use screen scraping or robotic process automation as a practical workaround for connecting otherwise isolated systems.
Why Do Businesses Use Screen Scraping?
One of the biggest reasons businesses use screen scraping is legacy system integration. Replacing older enterprise software can be expensive, disruptive, and technically complicated. Screen automation allows companies to retrieve information from existing systems while connecting that information to newer databases, cloud applications, or operational workflows.
Organizations also use scraping to automate repetitive administrative work. Employees might otherwise spend hours opening portals, checking information, copying records, and manually entering the same data somewhere else. Automating these actions can reduce repetitive tasks while allowing employees to focus on work requiring judgment or personal communication.
Another common use involves retrieving data from systems that provide no practical integration option. A supplier portal, financial dashboard, internal application, or specialized industry platform might contain valuable information but offer no API. Screen data extraction can provide temporary access without requiring major software redevelopment.
However, organizations should avoid treating scraping as the automatic solution whenever an integration problem appears. The apparent short-term convenience can create long-term maintenance costs if the automation frequently breaks, requires sensitive credentials, violates access rules, or processes confidential information without appropriate safeguards.
Why Can Screen Scraping Be Risky?
Reliability is one of the biggest screen scraping risks. Automation often relies on finding particular interface elements in specific locations or structures. If developers redesign a page, rename a field, introduce a popup, or adjust the login process, the automation may no longer know where to find the information it needs.
Incorrect data extraction can be even more dangerous than complete failure. A scraper might continue running after an interface change but begin collecting values from the wrong fields. If nobody notices immediately, incorrect information could flow into reports, financial systems, customer databases, or business decision-making processes.
Performance can also create problems. A scraping process may need to load complete pages and simulate numerous user actions to retrieve information that an API could return through a single structured request. Large-scale scraping can therefore consume significant computing resources and potentially place unnecessary load on the systems being accessed.
Finally, the organization operating the scraper becomes responsible for monitoring it carefully. Error detection, interface testing, logging, maintenance, credential management, data validation, and compliance reviews may all be necessary. Without proper oversight, what begins as a simple automation project can develop into an important operational dependency.
Security Risks of Screen Scraping
Many screen scraping workflows require authentication, which means the automation may need access to usernames, passwords, session tokens, or other credentials. Poorly protected credentials can become a serious security weakness, particularly when multiple automated processes share the same account or store login information insecurely.
Multi-factor authentication can make automated scraping more complicated. While stronger authentication improves account security, scraping workflows built around traditional username-and-password logins may struggle when applications require one-time codes, passkeys, device verification, security challenges, or other modern authentication methods.
Excessive account permissions create another concern. An automated scraper might only need to read a small amount of information while using an account capable of viewing or changing much more. If the credentials are compromised, attackers could potentially gain broader access than the automation itself actually requires.
Organizations can reduce these risks by following least-privilege access principles, protecting credentials in secure secrets-management systems, maintaining detailed activity logs, and separating automation accounts from employee accounts. Security teams should also regularly review which automated tools still require access and remove unnecessary permissions.
Privacy and Data Protection Concerns
Screen scraping can create privacy concerns when personal information is involved. Customer names, contact details, financial records, medical information, employee information, account identifiers, and other sensitive data might be displayed within an application and automatically transferred somewhere else during the scraping process.
The fact that information is visible to an authorized user does not automatically mean it can be collected, stored, shared, or reused without limitations. Organizations need to understand why the data is being processed, who can access it, where it will be stored, and how long it should be retained.
Data minimization is particularly important. A scraper should ideally collect only the information necessary for its intended purpose instead of capturing entire screens or complete customer records. Limiting data collection reduces unnecessary exposure and can simplify security, compliance, and information-governance responsibilities.
Businesses handling regulated or sensitive information should involve their privacy, security, compliance, and legal teams before implementing scraping automation. Requirements can vary by jurisdiction, industry, contractual relationship, and type of information being processed, making a one-size-fits-all approach inappropriate.
Legal and Compliance Risks to Consider
Screen scraping can also raise questions about authorization and permitted access. Websites, platforms, subscription services, and business applications may have terms defining how users or automated tools can access their systems. Automated extraction that conflicts with those rules could create contractual or legal complications.
The source of the data also matters. Publicly visible information does not necessarily mean every possible method of automated collection or commercial reuse is automatically permitted. Intellectual property, database rights, privacy rules, contractual restrictions, and computer-access laws can differ significantly between jurisdictions and situations.
Internal scraping requires governance as well. Employees may technically have permission to access business information through an application, but that does not always mean an automated system should duplicate the information into another database. Data classification and retention requirements may still apply.
For high-risk projects, businesses should review the specific source, information type, access method, purpose, and relevant agreements before deployment. Legal considerations surrounding automated data collection can be highly context-dependent, so professional advice may be necessary when large-scale or sensitive scraping is involved.
Why Screen Scraping Can Be Difficult to Maintain
One major weakness of screen scraping is its dependency on interface design. A workflow may expect a login field at a particular location, a certain button label, or a table with a particular structure. Even seemingly minor design changes can disrupt the sequence the automation expects.
Dynamic websites make this challenge even greater. Modern applications frequently load content asynchronously, personalize layouts, introduce temporary notifications, run experiments, or adjust interface components based on device size. Automation that worked correctly yesterday may encounter slightly different conditions the next day.
Maintenance therefore becomes an ongoing cost rather than a one-time development task. Teams may need automated testing, alerts, error logs, version controls, and fallback procedures to determine when a scraping workflow has stopped operating correctly. Critical processes may also need human review when unusual conditions appear.
These maintenance requirements are why screen scraping is often better treated as an integration workaround rather than the ideal long-term architecture. When reliable APIs, database integrations, data exports, or officially supported connectors become available, migrating away from fragile interface-based automation can improve operational stability.
How to Reduce Screen Scraping Risks
The first step is deciding whether scraping is actually necessary. Businesses should investigate supported APIs, database connections, export functions, webhooks, official integrations, and automation connectors before building a screen-based solution. A structured integration will often provide better reliability, security, and long-term maintainability.
When scraping is unavoidable, collect only the minimum amount of information required. Avoid unnecessarily storing complete pages, sensitive information, or authentication details. Access permissions should also be limited so the automated account can perform its specific task without receiving broader system privileges.
Monitoring is equally important. Organizations should validate extracted information, track failed workflows, record unexpected interface changes, and automatically flag unusual results. Important processes should not silently continue when the automation begins collecting missing, duplicated, or incorrectly mapped information.
Finally, build an exit strategy. A temporary scraper can easily become permanent if nobody reviews it later. Document why the automation exists, which systems it connects, who owns it, what information it handles, and whether a supported integration could eventually replace it.
When Should You Use an API Instead?
If the service provides a supported API capable of delivering the information you need, it will usually be the better integration option. APIs are specifically designed for software-to-software communication and generally provide more predictable data structures, authentication controls, documentation, and error handling than screen scraping.
APIs can also reduce dependence on visual page layouts. A company may completely redesign its user interface while continuing to support the same API endpoints. A screen scraper could break immediately after the redesign, while an API-based integration may continue functioning without any changes.
Performance and scalability are other major advantages. Instead of opening complete pages and simulating user actions, an application can make focused requests for specific information. This typically makes data exchange more efficient and easier to monitor when businesses need to process larger volumes of information.
Screen scraping remains useful when APIs do not exist, particularly when working with legacy applications and closed enterprise systems. Even then, organizations should periodically investigate whether a safer official integration has become available rather than maintaining an increasingly complicated scraping workflow indefinitely.
Is Screen Scraping Still Relevant Today?
Screen scraping remains relevant because digital transformation does not happen evenly. Many businesses continue to depend on older software, specialized applications, supplier portals, government systems, and industry platforms that provide limited integration options. Automation can extend the useful life of these systems while organizations modernize gradually.
Robotic process automation has also made screen-based automation more sophisticated. Modern tools can identify interface objects, interpret visual elements, handle workflow conditions, and connect extracted information with cloud applications. Some systems increasingly incorporate artificial intelligence and computer vision to make interface recognition more adaptable.
Even with these advances, the fundamental limitations remain. AI may help software recognize changing layouts, but it does not automatically solve issues involving authorization, sensitive data, legal restrictions, account security, or incorrect extraction. Better recognition technology should therefore not replace proper governance and validation.
The strongest approach is usually to view screen scraping as one tool within a broader integration strategy. It can solve genuine interoperability problems, but organizations should understand exactly why they are using it and whether safer, more stable, or officially supported alternatives could accomplish the same goal.
Final Thoughts on Screen Scraping
Screen scraping can be an effective way to automate information transfer when applications cannot communicate directly. It is especially useful for legacy software, repetitive administrative workflows, closed platforms, and situations where structured APIs or supported integrations simply do not exist.
At the same time, screen scraping should not be viewed as a completely invisible shortcut. Interface changes, authentication requirements, privacy concerns, data errors, legal restrictions, and ongoing maintenance can turn a seemingly simple automation into a significant business dependency.
Organizations considering scraping should evaluate both immediate benefits and long-term costs. Security controls, data validation, access permissions, monitoring, compliance reviews, and maintenance ownership should be designed into the workflow instead of added only after problems occur.
Ultimately, screen scraping works best when used deliberately. When no cleaner integration exists, it can connect otherwise isolated systems and reduce repetitive work. When a reliable API or supported data connection is available, however, choosing the structured integration will usually create a safer and more sustainable solution.
Frequently Asked Questions
Is screen scraping the same as web scraping?
No. Web scraping generally extracts information from website code or HTML structures, while screen scraping focuses more heavily on information displayed through a user interface and may simulate human interaction.
Is screen scraping illegal?
Screen scraping itself is not automatically illegal, but legality depends on factors such as authorization, data type, contractual terms, jurisdiction, privacy requirements, and how the collected information is used.
Is screen scraping safe?
It can be used safely when appropriate security controls are implemented, but poorly designed scraping can expose credentials, sensitive information, or inaccurate data and create operational vulnerabilities.
Why do companies still use screen scraping?
Companies commonly use it to connect legacy applications, automate repetitive tasks, retrieve information from systems without APIs, and transfer data between platforms that cannot communicate directly.
What is the best alternative to screen scraping?
A supported API is usually the preferred alternative because it provides structured data access, stronger integration controls, greater reliability, easier maintenance, and better scalability.