
DRP Meaning: Disaster Recovery Plan Explained
A DRP, or Disaster Recovery Plan, is a documented strategy that explains how an organization will restore critical technology, data, applications, and IT operations after a serious disruption. The disruption might come from ransomware, hardware failure, a cloud outage, a natural disaster, human error, power loss, or another event that makes important systems unavailable. A strong disaster recovery plan does more than say that backups exist; it identifies what must be recovered first, who is responsible, where recovery will happen, and how quickly important services should return. As businesses depend more heavily on cloud platforms, digital transactions, remote work, and interconnected applications, disaster recovery has become a central part of operational resilience and cybersecurity planning.
Modern disaster recovery also recognizes that restoring technology is rarely as simple as turning servers back on. Applications depend on databases, identity systems, networks, cloud services, third-party providers, encryption keys, configurations, and other components that must be recovered in the correct order. Organizations therefore use concepts such as Recovery Time Objective (RTO), Recovery Point Objective (RPO), business impact analysis, backup testing, failover, redundancy, and recovery priorities to build realistic plans. NIST describes disaster recovery planning within the wider discipline of information system contingency planning and emphasizes recovery requirements, testing, training, and maintenance. Understanding these concepts makes DRP much easier to translate from a technical document into a practical business capability.
What Does DRP Mean in IT and Business?
DRP stands for Disaster Recovery Plan, a written plan that guides an organization through restoring information systems and technology services after a major disruption. NIST’s glossary describes a disaster recovery plan as a written plan for recovering information systems following significant hardware or software failure or destruction of facilities. In practical business terms, the DRP answers questions such as which systems must be restored, who performs each recovery task, which backups or alternate environments should be used, and when operations can safely resume. The objective is not necessarily to prevent every outage, because some disruptions cannot be avoided, but to reduce the operational damage when an incident does occur.
A disaster can mean different things depending on the organization and the technology involved. A regional flood may damage a physical data center, while a ransomware attack can make systems unavailable even when every server remains physically intact. Cloud platform outages, database corruption, failed software deployments, stolen credentials, accidental deletion, telecommunications failures, and major hardware breakdowns can also trigger disaster recovery procedures. This broader definition is important because DRP should not be written exclusively around fires, earthquakes, or other physical disasters. Modern recovery planning must account for cyber incidents and digital dependencies because organizations can experience severe operational disruption without any visible damage to offices or equipment.
The scope of a DRP is usually focused on technology recovery rather than every activity required to keep the entire organization functioning. It may cover servers, cloud workloads, databases, networks, identity services, storage systems, business applications, backups, communication platforms, and supporting infrastructure. The plan should explain the relationships between these components because restoring one system can be useless if another dependency remains unavailable. For example, restoring an application server may not help employees if its database, authentication service, or internet connectivity has not recovered. Mapping dependencies allows recovery teams to establish a sequence that restores complete business services rather than isolated pieces of technology that cannot yet perform useful work.
DRP also provides structure during situations when teams may otherwise make rushed or contradictory decisions. During a serious outage, employees may be under pressure from customers, executives, regulators, partners, or internal departments demanding immediate answers. A documented plan clarifies decision authority, escalation procedures, technical responsibilities, communication channels, and recovery priorities before that pressure arrives. Teams can then follow tested procedures instead of designing a recovery strategy during the incident itself. The plan does not eliminate the need for professional judgment because real disruptions rarely happen exactly as expected, but it provides a reliable starting point that reduces confusion and makes coordination easier.
The value of a disaster recovery plan therefore lies in preparedness rather than documentation alone. A beautifully written DRP that employees cannot access during an outage, contains outdated contact information, or depends on backups that have never been restored provides little protection. Effective disaster recovery requires technology, documented procedures, trained people, tested backups, and organizational commitment to keeping the plan current. CISA’s ransomware guidance similarly recommends maintaining recovery-related documentation and regularly testing backups in disaster recovery scenarios rather than assuming stored copies will work. The strongest DRPs are living operational resources that teams practice and improve instead of documents created only to satisfy an audit requirement.
How Does a Disaster Recovery Plan Work?
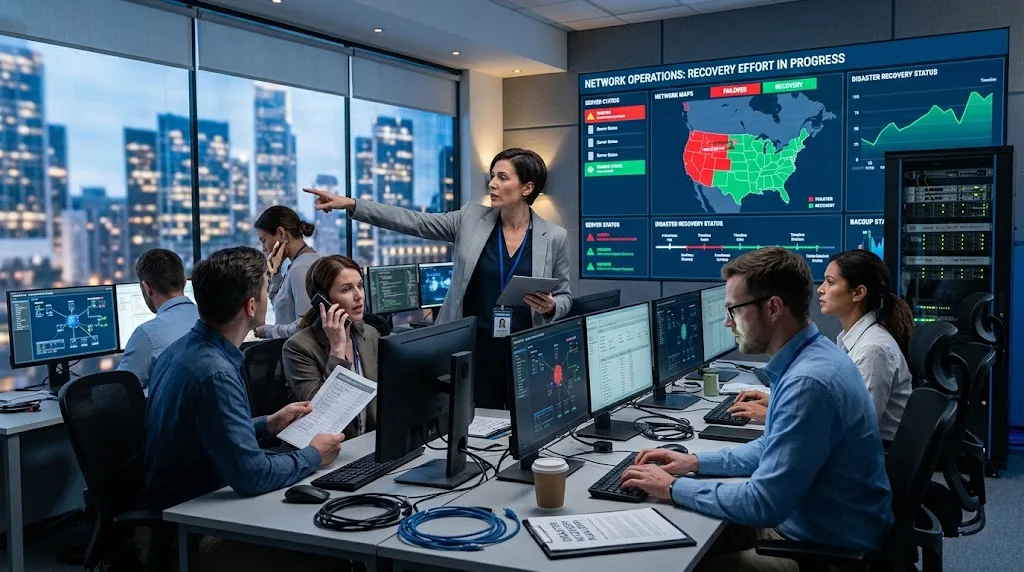
A disaster recovery plan normally begins with detection and assessment because the organization first needs to understand what has happened. An outage affecting one application may require a very different response from ransomware spreading across an enterprise network or a physical event that makes an entire facility unavailable. Technical teams gather information about affected systems, the likely cause, operational impact, and whether the disruption is still spreading. Decision-makers then determine whether ordinary incident management can restore the service or whether formal disaster recovery procedures should be activated. Clear activation criteria are useful because waiting too long can increase downtime, while declaring a full disaster for every minor interruption can waste resources and create unnecessary disruption.
After activation, the recovery team focuses on containment and stabilization when necessary. In cyber incidents, this may mean isolating compromised systems, restricting network communication, disabling affected accounts, or creating a clean recovery environment before restoration begins. CISA’s ransomware guidance recommends identifying and isolating impacted systems before reconnecting restored services so clean environments are not infected again. Physical disasters may require different actions, such as confirming facility safety, switching to an alternate site, or rerouting network connectivity. Recovery teams must understand the nature of the incident because restoring systems immediately can be counterproductive when the original threat, corrupted configuration, or infrastructure failure remains active.
The next stage is restoring critical infrastructure according to previously established priorities. Foundational services such as networks, identity management, DNS, storage, virtualization, cloud connectivity, or security monitoring may need to return before business applications can operate properly. Databases and application servers can then be recovered according to their dependencies and agreed recovery objectives. Organizations with failover technology may switch workloads to a secondary environment, while others may rebuild systems from backups, templates, or infrastructure-as-code configurations. The exact strategy depends on budget, architecture, business requirements, and acceptable downtime. The important point is that recovery follows a planned sequence rather than simply restoring whichever system happens to be easiest first.
Validation comes after technical restoration because a running server does not automatically mean a business service is usable. Recovery teams should verify data integrity, authentication, integrations, transactions, network connectivity, security controls, and application functionality before declaring a service restored. Business representatives can help confirm that essential workflows operate correctly from the user’s perspective. For example, an e-commerce platform might appear healthy technically while payment processing or inventory synchronization remains unavailable. Validation prevents teams from announcing recovery prematurely and helps uncover hidden dependencies that were missed during planning. Security teams may also need to confirm that restored systems are free from known compromise before reconnecting them to production environments.
The final stage involves returning to normal operations and learning from what happened. Temporary systems or alternate sites may need to be transitioned back to primary environments after the immediate crisis has passed, and outstanding data may require synchronization or reconciliation. Teams should document what worked, what failed, which recovery steps took longer than expected, and whether actual restoration times met established objectives. CISA recommends documenting lessons learned from recovery activities so organizations can refine policies, plans, and future exercises. Post-incident analysis turns a disruption into an opportunity to strengthen resilience by updating procedures, technology, training, dependencies, and recovery assumptions before the next serious event occurs.
Core Components of an Effective Disaster Recovery Plan
An effective DRP begins with a clear inventory of the systems, applications, data, and infrastructure that support important business operations. Organizations cannot establish sensible recovery priorities if they do not know what technology they own or which processes depend on it. The inventory should include physical servers, virtual machines, cloud resources, databases, networks, SaaS platforms, endpoints, backups, authentication systems, and relevant third-party services. CISA recommends understanding both logical and physical assets and identifying the systems most critical to safety, revenue, or essential services. Asset information should also identify owners, technical contacts, dependencies, locations, configurations, and recovery resources so teams can act quickly during a disruption.
Roles and responsibilities form another essential DRP component because recovery can involve many teams working simultaneously. The plan should identify who has authority to declare a disaster, who coordinates technical recovery, who communicates with leadership, and who manages specific systems or vendors. Organizations may also assign responsibilities for cybersecurity, legal issues, facilities, communications, finance, customer service, and business validation depending on the scenario. Alternate contacts are important because the primary expert for a critical system may be unavailable during an actual emergency. Contact information should be accessible through offline or alternative methods because a plan stored only inside the unavailable corporate network may become impossible to use when employees need it most.
Recovery procedures provide the practical instructions that turn strategy into action. These procedures may explain how to fail over a database, restore a server image, rebuild cloud infrastructure, recover files, configure network connections, verify security settings, or start applications in the correct sequence. Instructions should be detailed enough for trained personnel to follow without relying entirely on the memory of one administrator. Screenshots, configuration references, system diagrams, scripts, backup locations, and vendor documentation can improve usability when appropriate. However, procedures should also avoid embedding sensitive passwords or secrets directly in widely accessible documents. The DRP should instead explain how authorized recovery personnel obtain protected credentials through secure emergency access processes.
Communication plans are equally important because technology recovery happens within a broader business crisis. Employees need to know which systems are unavailable and what temporary processes they should use, while executives may need estimated recovery progress and customer impact. Customers, suppliers, regulators, insurers, law enforcement, or external partners may also require communication depending on the nature of the incident. The DRP should identify approved communication channels, escalation routes, message ownership, and alternatives if normal email or collaboration tools become unavailable. Out-of-band communication can be particularly important during cyber incidents because compromised systems may expose internal conversations to attackers or simply be unavailable to employees trying to coordinate recovery.
A good DRP also documents recovery resources and logistical requirements rather than assuming everything will be available during an emergency. This information can include backup systems, alternate facilities, cloud subscriptions, spare hardware, network diagrams, installation media, software licenses, encryption keys, recovery scripts, emergency vendor contacts, and replacement equipment procedures. CISA recommends retaining offline resources such as critical system images and documentation that can support rebuilding after ransomware or other destructive incidents. Organizations should periodically confirm that these resources remain usable because licensing changes, obsolete hardware, expired certificates, unsupported software, or forgotten credentials can turn an apparently complete recovery strategy into an unexpected failure.
RTO, RPO, and Business Impact Analysis Explained
A Recovery Time Objective, or RTO, describes how long a system or resource can remain unavailable before the disruption creates unacceptable impact. NIST defines RTO as the maximum amount of time a system resource can remain unavailable before unacceptable effects occur on supported business processes or related resources. If an online ordering platform has an RTO of two hours, the recovery strategy should be capable of returning that service within approximately that window under the scenarios the organization has planned for. Shorter RTOs usually require faster and more expensive recovery technology, which is why organizations should set objectives based on business needs rather than choosing extremely aggressive numbers for every application.
A Recovery Point Objective, or RPO, measures acceptable data loss rather than downtime. NIST describes RPO as the point in time before a disruption to which data should be recoverable, based on available backup information. If a database has an RPO of fifteen minutes, the organization should design backup or replication processes so a recovery would normally lose no more than about fifteen minutes of recent data. A system with a twenty-four-hour RPO could potentially restore from the previous day’s backup instead. RPO therefore influences backup frequency, replication, storage architecture, and cost, while RTO primarily influences how quickly systems must become available again.
RTO and RPO should not be chosen by the IT department in isolation because they represent business tolerance for disruption and data loss. Finance, operations, customer service, sales, compliance, cybersecurity, and other stakeholders may experience very different consequences when a system fails. A payroll system might tolerate several hours of downtime on most days but become extremely critical immediately before payroll processing, while an emergency communication platform may require near-continuous availability. Business leaders should therefore help determine which processes truly need aggressive recovery targets. This collaboration prevents technology teams from overspending on systems that can tolerate delay while underprotecting applications whose interruption could create severe financial, operational, safety, or reputational consequences.
A Business Impact Analysis, commonly called a BIA, provides the structured analysis needed to establish these priorities. NIST’s contingency planning guidance places business impact analysis among the core activities used to determine system requirements and recovery priorities. A BIA examines which business processes depend on specific systems, how the impact of an outage increases over time, and what resources are required for recovery. It may consider revenue loss, customer disruption, safety, contractual obligations, operational delays, regulatory exposure, and reputational harm. The result helps organizations identify critical systems and set realistic recovery objectives instead of assuming every application deserves the same level of protection.
Organizations should also understand maximum tolerable downtime when prioritizing recovery. NIST uses Maximum Tolerable Downtime (MTD) to describe the total period of disruption a mission or business process can accept before the impact becomes intolerable, and notes that RTO should generally fit within that larger limit. Recovery plans may need additional time after technical restoration for employees to reconcile data or resume normal workflows, which means an RTO set equal to the complete business tolerance could leave no margin for those activities. Using BIA, RTO, RPO, and downtime tolerance together creates measurable recovery requirements that can be tested instead of relying on vague promises such as “restore critical systems as quickly as possible.”
Backup and Recovery Strategies Used in a DRP
Backups are fundamental to disaster recovery because they provide recoverable copies of information when production data is deleted, corrupted, encrypted, or destroyed. However, simply having a backup job configured does not prove that data can actually be restored when required. Organizations should monitor backup completion, investigate failures, protect backup credentials, and perform restoration tests that verify both data integrity and recovery procedures. CISA recommends maintaining offline, encrypted backups of critical data and regularly testing their availability and integrity in disaster recovery scenarios. Testing is particularly important because organizations sometimes discover during emergencies that backups are incomplete, corrupted, inaccessible, or dependent on infrastructure that failed alongside the original systems.
Offline and immutable backups can provide additional protection against ransomware and malicious deletion. Backups continuously accessible from the production network may be discovered and encrypted by attackers who obtain sufficient privileges, leaving organizations without clean recovery data. CISA therefore emphasizes offline backup copies and also recommends using protections such as immutable storage where appropriate so information cannot easily be altered or deleted. Organizations often combine several backup approaches so one failure or attack does not eliminate every recovery option. Separation of credentials is also valuable because compromise of a normal administrator account should not automatically provide the ability to destroy every backup copy.
Replication is another recovery strategy, but it solves a somewhat different problem from traditional backup. Replication continuously or periodically copies data or systems to another location so the secondary environment can take over more quickly when primary infrastructure fails. This can support aggressive RTO and RPO requirements because less rebuilding may be required after an outage. However, replication can also copy corruption, accidental deletion, or malicious encryption to the secondary environment if safeguards are weak. For that reason, replication should not automatically replace independent backup copies. Strong disaster recovery architectures often combine rapid replication for availability with isolated backups that provide historical recovery points when the latest replicated state is no longer trustworthy.
Failover allows workloads to switch from unavailable infrastructure to an alternate environment. The alternate environment might be another data center, availability zone, cloud region, secondary server, or disaster recovery platform operated by a service provider. Some failover systems operate automatically, while others require approval because an unnecessary switch can create complications or additional costs. Failback must also be planned so services can eventually return to normal infrastructure after the primary environment becomes stable. Organizations should test both directions because successfully failing over once does not guarantee that data, network routing, authentication, or application dependencies will behave correctly when systems are moved back afterward.
Modern recovery strategies increasingly use automation and infrastructure as code to rebuild environments more consistently. Cloud servers, networks, security groups, load balancers, and other resources can often be created from version-controlled templates rather than reconstructed manually from memory. CISA’s ransomware guidance specifically notes infrastructure as code as one way organizations can support rapid cloud resource redeployment, while also recommending offline protection for important template files. Automation can reduce recovery time and configuration errors, but organizations still need protected source files, credentials, software dependencies, and tested procedures. Automated recovery is valuable only when the automation itself remains available, secure, and compatible with the environment that must be rebuilt.
DRP vs Business Continuity and Incident Response Plans
A disaster recovery plan and a Business Continuity Plan (BCP) are closely related, but they do not have identical purposes. Disaster recovery concentrates primarily on restoring technology, information systems, data, and technical infrastructure after a serious disruption. Business continuity considers how essential business operations can continue during that disruption, even when normal technology, offices, suppliers, or personnel are unavailable. For example, a DRP might explain how the accounting platform will be restored, while the business continuity plan explains how finance employees will process urgent payments while the system remains offline. The two plans therefore support each other, with DRP providing technology recovery and BCP addressing the wider continuity of essential organizational activities.
Business continuity planning may include alternate workplaces, manual procedures, replacement suppliers, emergency staffing, communications, transportation, facilities, and other non-IT requirements. A manufacturing company could have technically healthy computer systems while production stops because a physical facility cannot operate, demonstrating why technology recovery alone cannot guarantee business continuity. Conversely, employees may have access to an alternate office but remain unable to work because critical applications are unavailable. Organizations should map these relationships so DRP timelines support the wider continuity requirements of essential business processes. Recovery objectives derived from the BIA help connect technical restoration with the period during which manual workarounds or alternate processes can realistically sustain operations.
An Incident Response Plan (IRP) serves another different but related function, especially during cybersecurity events. Incident response focuses on detecting, analyzing, containing, eradicating, and responding to security incidents such as malware infections, unauthorized access, or data breaches. Disaster recovery becomes more prominent when the incident has caused substantial system or data loss that requires rebuilding or restoration. A ransomware event may therefore begin as a cybersecurity incident and later activate disaster recovery procedures once affected systems are isolated and clean recovery begins. CISA’s ransomware guidance combines response and recovery activities because successful cyber recovery depends on preventing restored systems from being compromised again.
The plans should therefore be coordinated rather than written independently by different teams that never compare assumptions. An incident response plan might require compromised servers to remain isolated for forensic investigation, while a DRP could assume those same servers can immediately be reused, creating a conflict during a real event. Similarly, business continuity might assume an application returns within four hours even though technical recovery testing shows restoration usually takes ten hours. Cross-functional exercises help uncover these contradictions before an actual emergency. Security, IT operations, business continuity, risk, legal, communications, and business leaders should understand where responsibilities transfer between plans and which individual has authority when objectives conflict.
Organizations may also maintain crisis management plans, emergency response plans, communications plans, continuity of operations plans, and specialized plans for particular facilities or risks. The goal is not to create as many documents as possible but to establish clear responsibilities across the entire response and recovery lifecycle. NIST’s contingency planning guidance specifically discusses the relationships between information system contingency planning and other security or emergency management plans. Smaller organizations may combine several areas into one practical resilience plan, while large enterprises often need specialized documents because of their scale. Whatever structure is chosen, employees should understand which plan applies, how plans connect, and where authoritative recovery information is stored.
Cloud and Cyber Disaster Recovery in Modern Organizations
Cloud computing has changed disaster recovery by making secondary infrastructure easier to provision without maintaining a complete physical data center in another location. Organizations can replicate workloads across regions, create backups in cloud storage, maintain standby environments, or rebuild infrastructure on demand after a disruption. This flexibility can lower some barriers to sophisticated recovery strategies, particularly for businesses that previously could not justify duplicate hardware. However, moving systems to the cloud does not automatically create disaster recovery. Organizations still need to configure backups, replication, access controls, network connectivity, recovery automation, and geographic separation according to their requirements. They should also understand the cloud provider’s shared responsibility model instead of assuming the provider protects every workload automatically.
Cloud disasters can also originate from configuration errors, compromised administrator accounts, deleted resources, software failures, or provider outages. A backup stored inside the same cloud account can be vulnerable if an attacker gains privileges that allow the primary workload and recovery copies to be deleted together. CISA recommends understanding cloud shared responsibility, protecting data with appropriate backup strategies, and considering features such as object locking or other controls against deletion and overwriting. Some organizations use separate accounts, regions, providers, or security boundaries to reduce correlated risk. The appropriate architecture depends on business requirements, but disaster recovery should always consider what could cause the primary and recovery environments to fail simultaneously.
Ransomware has also changed how organizations think about recovery because availability alone is no longer enough. Traditional DRP scenarios often assumed production infrastructure had failed while backup data remained trustworthy. Modern attackers may deliberately target backups, management systems, virtual infrastructure, identity services, and recovery tools to make restoration difficult. Organizations therefore increasingly separate backup administration from ordinary IT administration, protect recovery credentials, maintain immutable or offline copies, and create clean-room recovery environments. CISA’s guidance emphasizes isolation, offline backups, protected system images, and careful restoration of clean systems following ransomware incidents. Cyber recovery consequently combines disaster recovery principles with security investigation, containment, and validation.
Identity systems deserve particular attention because many cloud and enterprise applications depend on centralized authentication. If the organization’s directory service or cloud identity platform is compromised, attackers may retain access even after individual application servers are restored. Recovery plans should therefore document how administrators will regain trusted access, restore identity services, rotate credentials, and verify privileged accounts after a cyber incident. Break-glass or emergency accounts may provide necessary access when ordinary authentication mechanisms fail, but those accounts must be protected carefully and tested periodically. Organizations should also know which applications depend on single sign-on so identity recovery is prioritized appropriately rather than discovered only after dozens of restored applications remain inaccessible.
Software-as-a-service platforms create another recovery question because customers do not normally control the underlying infrastructure. A SaaS provider may maintain high availability, but users can still lose data through accidental deletion, malicious actions, configuration mistakes, compromised accounts, or retention limitations. Organizations should review contractual recovery commitments, export options, backup capabilities, service-level agreements, and procedures for retrieving information during an outage. Critical SaaS platforms should be included in the BIA and DRP rather than excluded simply because another company hosts them. Disaster recovery responsibility does not disappear when technology is outsourced; it changes into a combination of technical controls, vendor management, contractual requirements, alternate processes, and data protection.
How to Create, Test, and Maintain a Disaster Recovery Plan
Creating a DRP begins with identifying critical business processes and the technology supporting them. Organizations should perform or update a business impact analysis, inventory systems, map dependencies, and establish priorities based on the consequences of downtime or data loss. Stakeholders should agree on RTO and RPO targets that reflect genuine business needs, then IT teams can evaluate whether existing technology is capable of meeting those targets. This order matters because buying backup or replication products before understanding requirements can produce an expensive architecture that protects the wrong systems. NIST’s contingency planning process similarly connects business impact analysis, preventive controls, recovery strategies, plan development, testing, training, and maintenance.
The organization can then select recovery strategies appropriate to each system’s importance. Mission-critical applications may justify near-real-time replication or standby infrastructure, while less important systems might reasonably be rebuilt from daily backups. Recovery strategies should address applications, databases, identity, networking, storage, cloud services, physical facilities where relevant, and third-party dependencies. Procedures should be written clearly enough that trained staff can execute them during high-pressure conditions. Teams should also document assumptions, such as required internet connectivity or access to particular vendors, because assumptions that are not stated can become hidden single points of failure when the real event does not match the expected scenario.
Testing turns the written DRP into an evidence-based recovery capability. A discussion-based tabletop exercise can help leaders walk through responsibilities and identify missing decisions, while technical recovery tests can verify whether backups, failover, networks, authentication, and applications actually work. More advanced exercises may restore complete services in isolated environments or simulate the loss of a primary location. Different test types can be used according to risk and operational tolerance, but every critical system should receive meaningful recovery validation. CISA recommends regularly exercising incident response and recovery processes and testing backup procedures rather than treating stored backup copies as sufficient protection.
Training is important because employees should understand their role before an emergency begins. Technical teams need practice using recovery tools, while business teams should know how to validate restored applications or activate temporary work procedures. Executives need familiarity with disaster declaration and escalation decisions, and communications teams should understand how updates will be delivered when ordinary channels are unavailable. Cross-training can reduce dependence on one expert who may be unreachable when an incident occurs. Organizations can also maintain concise recovery checklists alongside detailed technical documentation because responders under pressure may benefit from clearly sequenced actions rather than having to search through hundreds of pages during the first critical minutes.
Finally, the DRP must be maintained as systems and organizations change. New applications, cloud migrations, office moves, acquisitions, network redesigns, staffing changes, and vendor replacements can make recovery procedures obsolete surprisingly quickly. Reviews should occur on a scheduled basis and after major technical or organizational changes, recovery tests, or real incidents. Contact details, diagrams, dependencies, backup locations, credentials processes, and recovery objectives deserve particular attention because small inaccuracies can create significant delays. Disaster recovery planning is therefore a continuous resilience program rather than a one-time documentation project. Organizations that regularly test, measure, update, and improve their plan are far more likely to recover predictably when a serious disruption eventually occurs.
Frequently Asked Questions
What does DRP stand for?
DRP stands for Disaster Recovery Plan. It is a documented strategy for restoring critical IT systems, applications, infrastructure, and data after a major disruption such as ransomware, equipment failure, natural disaster, or cloud outage.
What is the main purpose of a disaster recovery plan?
The main purpose of a DRP is to reduce downtime and data loss by establishing recovery priorities, responsibilities, procedures, and technology before a disaster occurs. It helps teams restore essential digital services in a controlled and predictable way rather than improvising during an emergency.
What are RTO and RPO in disaster recovery?
RTO, or Recovery Time Objective, indicates how quickly a system should be restored after disruption, while RPO, or Recovery Point Objective, describes how much recent data loss can be tolerated. These objectives help organizations choose appropriate backup, replication, failover, and recovery technologies.
What is the difference between DRP and BCP?
A Disaster Recovery Plan focuses mainly on restoring IT systems and technology, while a Business Continuity Plan addresses how essential business operations will continue during a disruption. The two plans should work together because business processes frequently depend on technology being restored within specific time limits.
How often should a disaster recovery plan be tested?
Testing should occur regularly and whenever significant systems, infrastructure, vendors, or business requirements change. The appropriate frequency depends on organizational risk, but critical backups and recovery processes should be tested often enough to provide evidence that recovery objectives can genuinely be achieved.